BY Juan Francisco Figueredo
The Spec Was Perfect. The Data Disagreed.
The best-specified ticket I've seen this year had everything our playbook asks for. Every claim traced back to a source. Every open question had been escalated to product and ruled on, with the ruling cited right there in the ticket. Null semantics stated in writing. Out-of-scope items named and parked. It was the Context Pipeline working exactly as designed. You could hand it to an agent and expect correct code back.
It was also wrong about the data in three ways before anyone wrote a line of code.
The feature computed a few derived metrics that users sort and filter lists by. The spec assumed a certain threshold field was always populated. It assumed the computed values couldn't go below zero. And it covered one category of record when production has several. None of this was careless. Each assumption read as settled, because it was written down, sourced, and approved. What nobody had done was open the repo where that data actually gets mapped, or run a single query against production, before writing the formulas.
Ambiguity was never the only enemy
Everything we publish on this site says that specification quality is the highest-leverage investment in an agentic SDLC, and I believe it. Agents don't absorb ambiguity the way people do. They execute whatever context you give them. So we built pipelines that squeeze ambiguity out: PRDs feed specs, specs feed architecture plans, those feed tickets, decisions get written back into the governing artifact, provenance logs rank sources with code as ground truth.
What that ticket taught me is that a spec can be internally perfect and externally wrong. The Context Pipeline resolves ambiguity — places where the artifact under-determines what to build. It has nothing that catches a false premise: a sentence that is precise, confident, cited, and factually wrong about the world it describes.
For application code that distinction rarely bites, because the world the spec describes is mostly the system itself, and code is ground truth. For data work, the world the spec describes is the data. And the data isn't in the repo.
Our source hierarchy names three classes: external standards, internal docs, source code. Data teams have a fourth, and it outranks the other three the same way code outranks a stale design doc. The schema says a column is nullable; only the warehouse knows it's actually null for 40% of rows in half your tenants. The code says coalesce(value, 0); only the data knows how often that zero is hiding a missing record rather than a real zero. A spec written from documents alone inherits every gap between what the documents believe and what the rows contain. Even a flawless one. Especially a flawless one, as it turns out.
Good specs make wrong premises travel further
This is the part I found uncomfortable. The old sloppy way — vague ticket, engineer figures it out — had an accidental safety net. The engineer went and looked. They opened the table, ran a few counts, noticed the weird values, asked someone why there were more record categories than the ticket mentioned. Implementation friction forced contact with reality.
A great spec removes that friction, which is the whole point of it. But then the builder, human or agent, has no reason left to look. The bad assumption about the threshold field wasn't a gap an agent would flag. It was an instruction an agent would faithfully execute. A cited wrong premise reads as settled. So the better your context pipeline gets, the more authority a false premise carries, and the further it travels before something hits production and a user asks why the worst possible value is sitting at the top of every list they sort.
And it ships quietly. Application bugs announce themselves — exceptions, failed requests, red tests. Data bugs ship green. The pipeline runs, the load succeeds, the dashboard renders, and the number is wrong. There's no test that knows what the right total for a tenant is, because nobody knows that up front. In a data platform, correctness is only ever observable by checking against something else that's live.
The missing gate: run the premises as queries
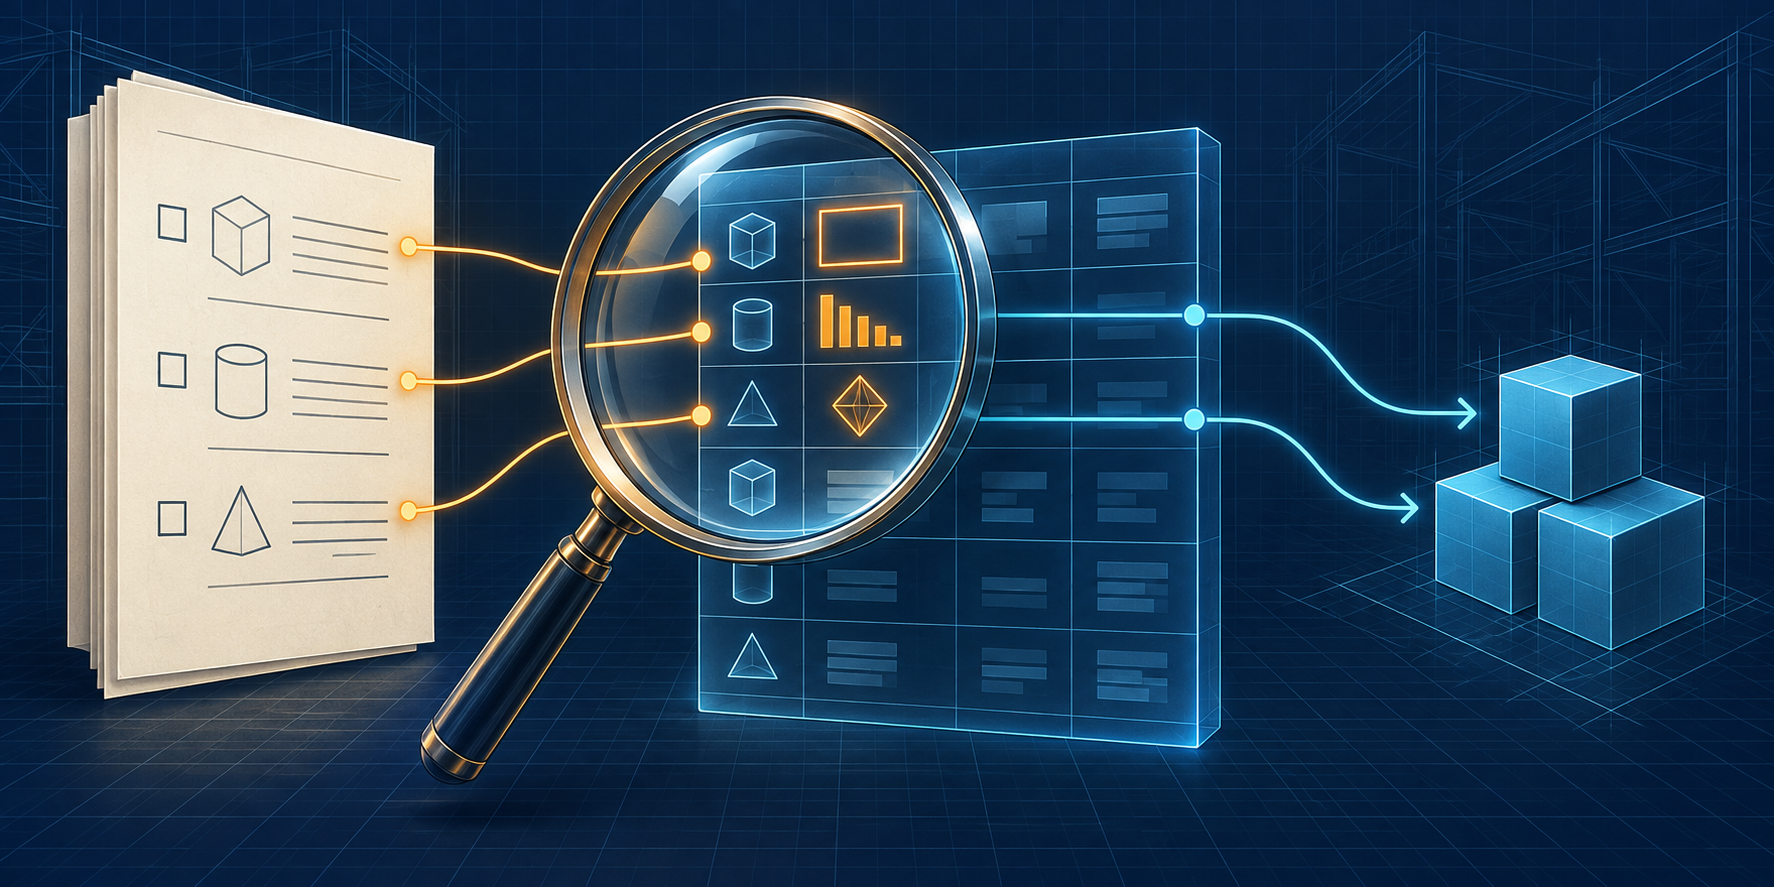
The fix we've landed on is boring, which is why I trust it. Before a data spec counts as shaped, its premises get run as queries.
Every data spec makes claims about the world, most of them implicit. This field is populated. This value can't be negative. This join is one-to-one. This entity has one variant. The exercise is to make those claims explicit and execute them. Not as tests after the build — as a gate on shaping, before the ticket is final:
- Is this field ever null, and in how many tenants?
- Do negatives occur? How many rows? Where?
- How many variants of this entity exist in production, and does the logic cover all of them?
- Does the "same" column mean the same thing everywhere, or did a
coalescethree tables upstream quietly change what it means?
Two years ago this would have been a hard sell. It's an afternoon of an engineer's time per ticket, spent before anyone has agreed the ticket is real. Agents collapse that cost. Give one read-only warehouse access and the spec draft, and asking it to pull out every checkable premise and verify it is a ten-minute pass. We've had an agent chase a single suspicious pattern across every tenant we run, in less time than checking one used to take. A bug report about one org becomes a verified statement about the whole fleet, and the spec inherits facts instead of beliefs.
The same rule now governs our debugging. No hypothesis graduates to root cause until a live query has ruled it in. Agents pattern-match confidently — on column names, on plausible causes, on what similar systems usually do — and the thing that makes them safe around data isn't better prompting. It's an environment where checking is cheaper than guessing, plus a norm that nothing data-shaped gets asserted from memory.
For what it's worth, that ticket got fixed exactly this way. Someone read the actual transformation in the actual repo, ran the actual rows, and the correction went back into the spec, cited like everything else. The pipeline worked fine. It just needed the fourth source plugged in.
The left half of the lifecycle needs warehouse access
If I could add one line to the playbook, it's this. We instinctively give warehouse credentials to Build and Validate, because that's where the SQL runs. But the expensive mistakes in that ticket were manufactured in Define and Shape, in rooms where the only open sources were documents. Every artifact upstream of code — PRD, spec, ticket — should be written within arm's reach of a read-only connection and an agent that knows how to use it.
We've said here before that specs are the new source code, and it holds. But we compile source code against something real before trusting it. A data spec deserves the same: compiled against the warehouse, premise by premise, while being wrong is still cheap.
Key premise: a specification can be internally perfect and externally false. For data teams, the data is a source the context pipeline has to read, not just describe.